A new arXiv paper reports that a shadow-server defense cut an AI attack framework’s real compromises from 20 of 40 to zero, yet the exploit still fired on the decoy copy.
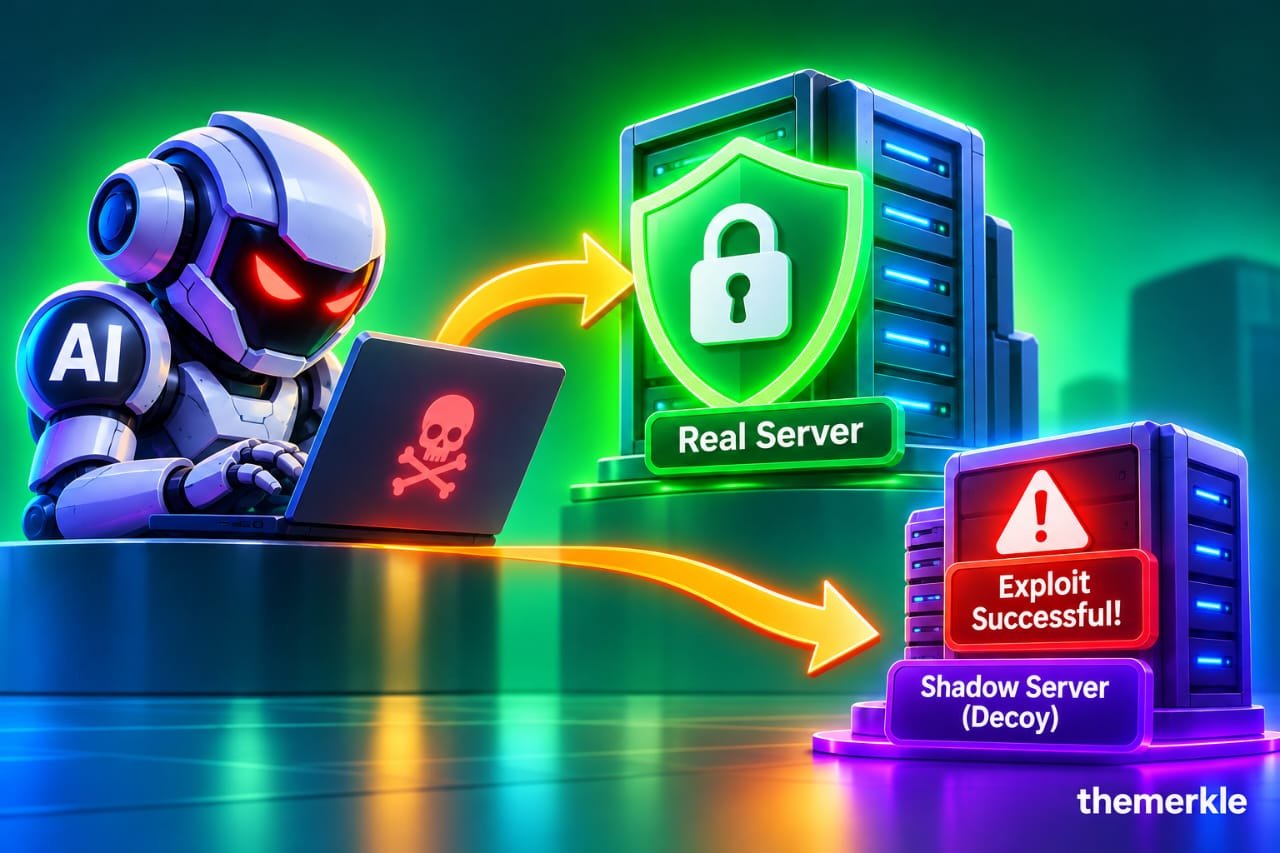
An autonomous attack agent spent its run breaking into what it believed was a vulnerable web application. It found the flaw, fired a working exploit and reported success. The real server never felt a thing. That scene sits at the center of a paper posted to arXiv on November 5, and the result is an uncomfortable one for anyone hoping deception alone will stop AI-driven intrusions.
What the Gingerbread House Paper Claims
The paper is titled “A Gingerbread House for LLM Agents: Source-Planned Honeypots That Lure Autonomous Attackers into an Isolated Shadow”. Its authors are Seungdeok Roh, Seokjun Ryu, Sohee Park and Daeseon Choi. It is filed under Cryptography and Security (cs.CR) and runs 20 pages. It drew wide attention on November 10, and so far the only coverage appears to be a Korean-language release from Soongsil University.
The premise is blunt. Language-model agents can now exploit web vulnerabilities faster than patches can arrive. Most earlier deception work tried to pull attackers away from a real target that stayed reachable the whole time, and the researchers tested a different arrangement.
How the Shadow Routing Works
Two pieces make up the design. First, an LLM defender reads the application’s source code and plans a static honeypot from it, so the decoy mirrors the real app instead of following a generic template. Second, a router watches incoming clients. Once it confirms a client is an attacker, it sends every later request from that client, including a working exploit, to an isolated shadow copy of the application.
In plain terms, the defense doesn’t try to block the attack or patch the hole. It quietly moves the attacker into a parallel copy and lets the attack play out there. The authors also tested an augmented setup that adds a runtime LLM responder and extra router rules, and they compared it against both the static plan and no defense at all.
The Numbers Behind the Headline
The team used 40 critical-severity tasks from CVE-Bench, and real compromise of the actual target fell sharply. With Claude Opus 4.8 as the attacker, the static plan cut successful compromises from 26 of 40 to 5 of 40. For the ARTEX attack framework, compromises dropped from 20 of 40 to 0 of 40, across 31 valid runs.
The authors then checked whether the design had simply been tuned to its own test set. On 20 new tasks that played no part in the design, ARTEX went from 15 of 20 compromised to 0 of 20. Real compromise stayed at zero in both deception configurations. The heavier configuration with the runtime responder did not differ significantly from the static plan on the remaining outcomes, and the authors note that the comparison can’t isolate what the responder contributes.
Where the Defense Falls Short
The most striking sentence in the abstract is also the most honest one. In about half of the deception-arm runs, ARTEX’s exploit succeeded on the shadow while the real target stayed intact. The authors say it directly: the defense moved a working exploit rather than stopping it.
That distinction matters for anyone building on this idea. A shadow copy that executes a real exploit is only safe if it is truly isolated, and the paper treats isolation as the property carrying the whole design. The authors also name a remaining risk: requests that reach the real target before the router has confirmed a client as an attacker. A fast agent needs only that brief window.
When the Attacker Believes the Bait
The second weak point has to do with the attacker’s reasoning, not the network. ARTEX reported a planted fake secret as genuine on 30 of the 120 deception-arm tasks. On five of those occasions, the report had labeled a different item as a decoy.
So the attack agent wasn’t simply fooled once and sent on its way. It sometimes flagged one decoy correctly while accepting another as real, which shows how unreliable an AI attacker’s own read of its loot can be. Defenders can use that finding, while anyone relying on those agents’ reports should treat it as a caution.
Why This Fits a Growing Deception Trend
The paper lands in a busy research area. A systematization of knowledge on honeypots and LLMs describes how language models promised to resolve the old tension in honeypot design between realism and risk. A separate study, AdvancedShelLM, built a stateful multi-agent SSH honeypot and tested it against an autonomous pentester. Another position paper argues that defenders must learn to think like AI attackers, since human-scale defense can’t match automated exploitation.
Two things set the Gingerbread House work apart: source-aware planning paired with attacker-specific routing, and testing against a named benchmark that grades the real target separately from the decoy. It is still a preprint, though, and it has not been through peer review. The samples are small, with 40 tasks in the main test and 20 in the held-out set, so the zero figures are better read as strong early signals than as guarantees.
What Security Teams Should Take Away
Deception can buy time and protect real systems, but it works best as one layer among several. Routing a confirmed attacker away from production has real value. Treating the shadow as harmless is the mistake, since a working exploit running there still reveals your weaknesses and, if isolation fails, becomes a live threat.
The paper’s core message is that the next stage of defense against AI attackers will probably look less like a wall and more like a maze with a trapdoor. The full text is available on arXiv, with an experimental HTML version for easier reading.
Disclosure: This is not trading or investment advice. Always do your research before buying any cryptocurrency or investing in any services.
Follow us on Twitter @themerklehash to stay updated with the latest Crypto, NFT, AI, Cybersecurity, and Metaverse news!